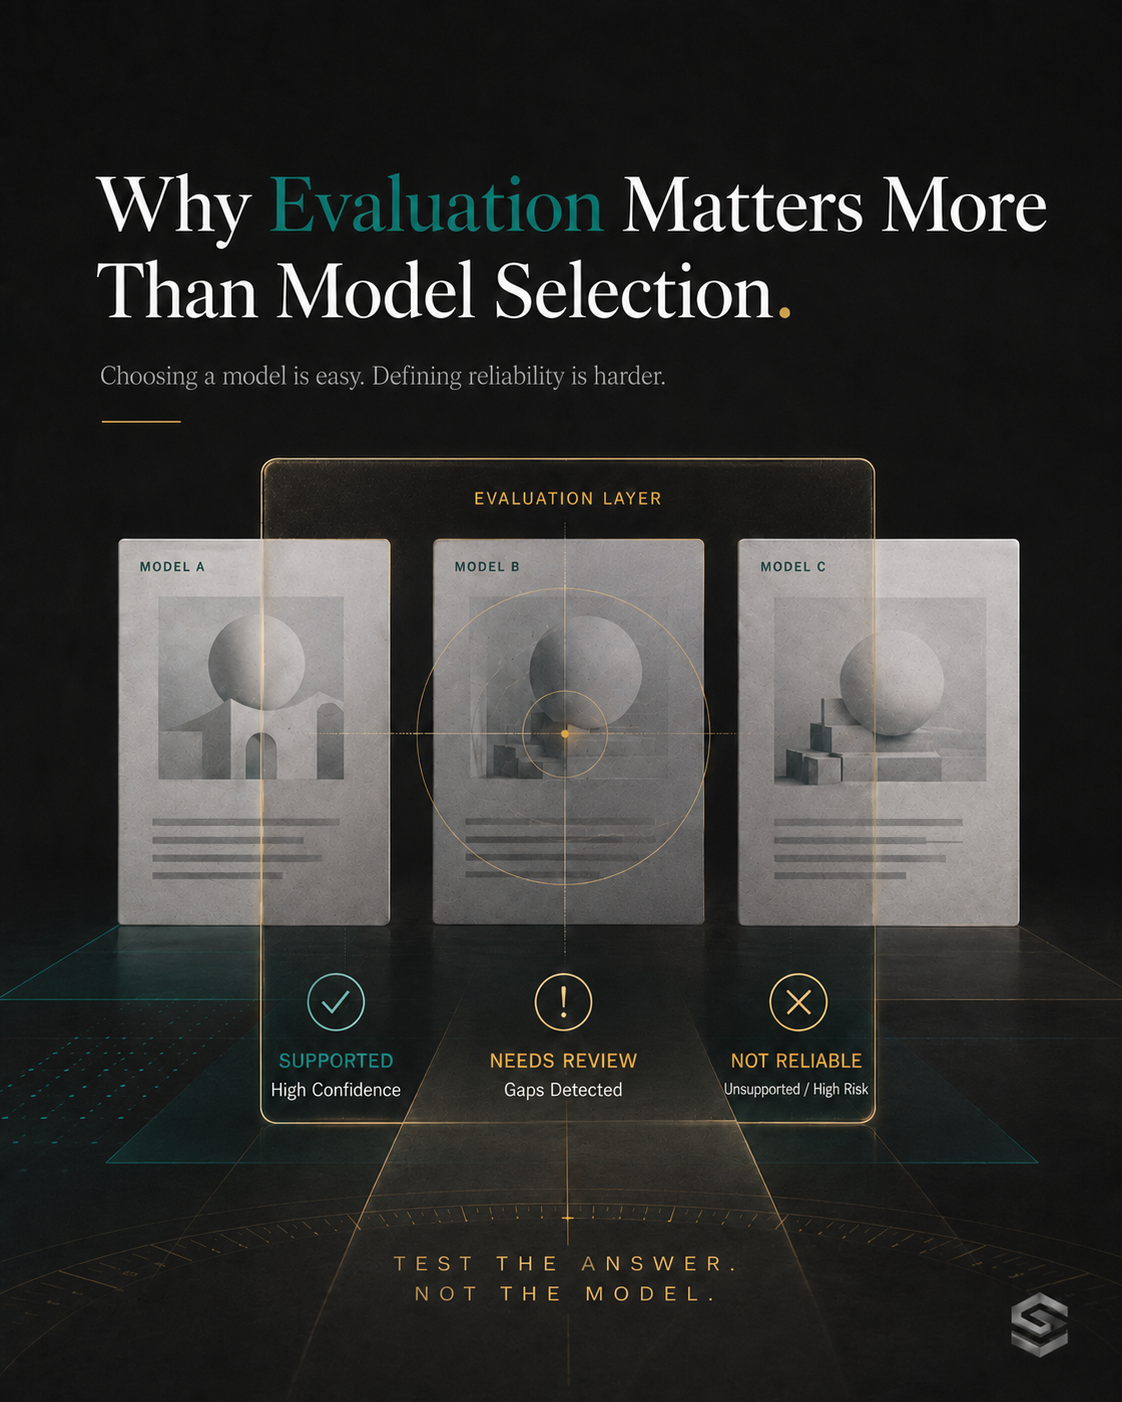
In enterprise AI, model selection often gets more attention than evaluation.
That is understandable. Models are visible, comparable and easier to discuss. But for most real enterprise use cases, the harder question is not which model looks better in general. It is whether the system is reliable enough for the specific decision or workflow it is meant to support.
A model can perform well in a benchmark and still fail inside a business process.
It may miss the relevant document. It may retrieve stale context. It may answer correctly but without enough evidence. It may produce an acceptable summary for a low-risk use case but an unsafe recommendation for a high-risk one.
Evaluation is how an organisation makes these differences visible before scale.
The evaluation question should not be only: is the answer good?
It should ask: good for what use case, under what evidence standard, with what failure modes, at what threshold, and with what human review or escalation path?
This requires representative test cases, clear rubrics, failure categories, business thresholds and ongoing monitoring after deployment.
The real issue is not whether AI can answer. It is whether the organisation knows when the answer is reliable enough to use.
That is why evaluation matters more than model selection.